Full text search over my archive means shipping a huge index to the browser. How do people keep this usable?
Split it in two. The list view needs titles, dates and counts, which is small and loads immediately. The full text is only needed the moment someone types, so it can be a separate file fetched on first keystroke.
The difference is the whole user experience: 0.2 MB before interaction, and the remaining megabytes only for people who actually search.
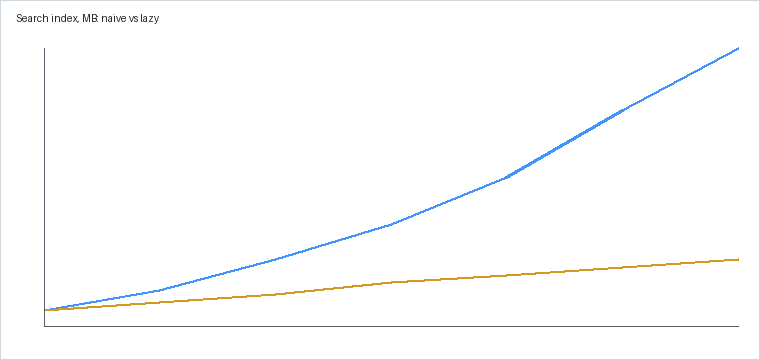
The flat line is the lazy version. It grows too, but nobody pays for it until they use it, and by then they have already decided the archive is worth searching.
Any trick for the search itself, or is substring matching enough?
For an archive this size, plain substring matching over a normalised copy is enough and has one large advantage: no index build step, no stemming surprises, no ranking to explain. The part worth spending effort on is showing the matching sentence under each hit, because that is what turns a list of titles into an answer.